Data Consistency and Replication in Distributed Systems: A Guide for Interview Preparation
Explore the critical aspects of ensuring data consistency and implementing data replication in distributed systems. This comprehensive guide covers various consistency models, replication strategies, and practical considerations for candidates preparing for technical interviews.

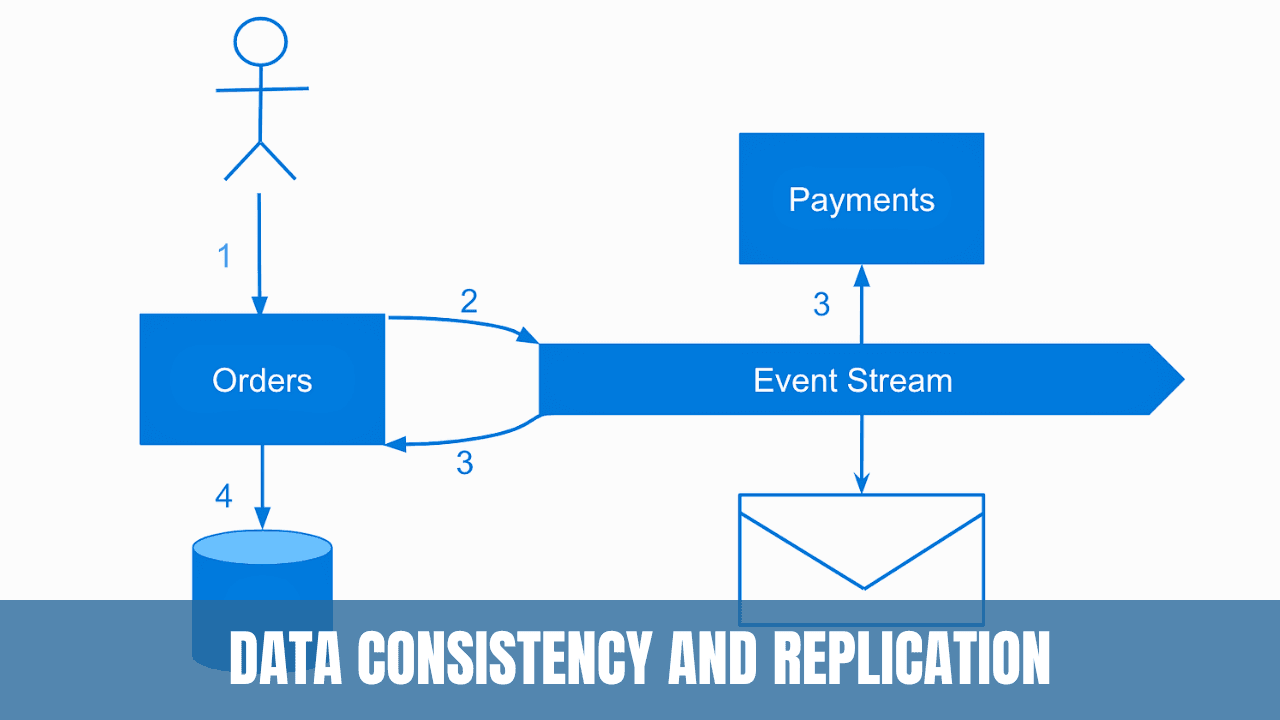
In the realm of distributed systems, data consistency and replication are critical concepts. This article focuses on how to ensure data consistency across various nodes in a distributed system and how to implement data replication to provide fault tolerance and increased availability. These principles are fundamental for candidates preparing for technical interviews in fields related to database management and distributed systems.
Data Consistency in Distributed Systems
Data consistency refers to the requirement that data remains uniform across a distributed system. This means that any read request for a particular data item must return the most recent write. Achieving data consistency in distributed systems can be complex due to the various challenges involved, including:
- Latency: The time it takes for data to propagate through the system.
- Concurrency: Handling simultaneous read and write operations.
- Network Failures: Ensuring consistency despite potential network issues.
There are different consistency models employed to handle these challenges, such as:
- Strong Consistency: Guarantees that all nodes see the same data at the same time.
- Eventual Consistency: Ensures that given enough time without new updates, all nodes will eventually converge to the same data.
- Causal Consistency: Maintains the order of related operations.
Data Replication
Data replication involves making copies of data and storing them across different parts of a distributed system. This strategy is crucial for:
- Availability: Ensuring data is accessible even if part of the system fails.
- Performance: Enhancing the speed of read operations by spreading requests across multiple copies.
- Fault Tolerance: Protecting against data loss due to hardware or software failures.
Different replication strategies are used to achieve these goals, including:
- Master-Slave Replication: One master copy is responsible for writes, and slave copies handle reads.
- Multi-Master Replication: Multiple nodes can accept write operations, with a protocol to handle conflicts.
- Quorum-Based Replication: Reads and writes are based on a majority (quorum) agreement between nodes.
Interview Considerations
When preparing for interviews, candidates should focus on:
- Understanding Various Consistency Models: Be ready to discuss the pros and cons of different consistency strategies.
- Explaining Replication Techniques: Understand different replication strategies and when to use them.
- Solving Real-World Problems: Demonstrate how to apply these concepts in practical scenarios, such as handling large-scale data.
Conclusion
Ensuring data consistency and implementing replication in distributed systems are complex tasks that demand an in-depth understanding of various models and techniques. Interviewees aiming to excel in these areas should be well-versed in these concepts, as they form the backbone of modern data management strategies. By focusing on the principles highlighted in this guide, candidates can confidently discuss and demonstrate their knowledge, positioning themselves as skilled professionals in the rapidly evolving field of distributed computing and data management.

Vishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy