Data Backup, Recovery, and Disaster Planning: A Comprehensive Guide for Database Management
Explore the crucial aspects of database management including data backup, recovery, and disaster planning. This guide provides an in-depth look into different strategies, techniques, and tools essential for protecting data, ensuring business continuity, and minimizing risk.

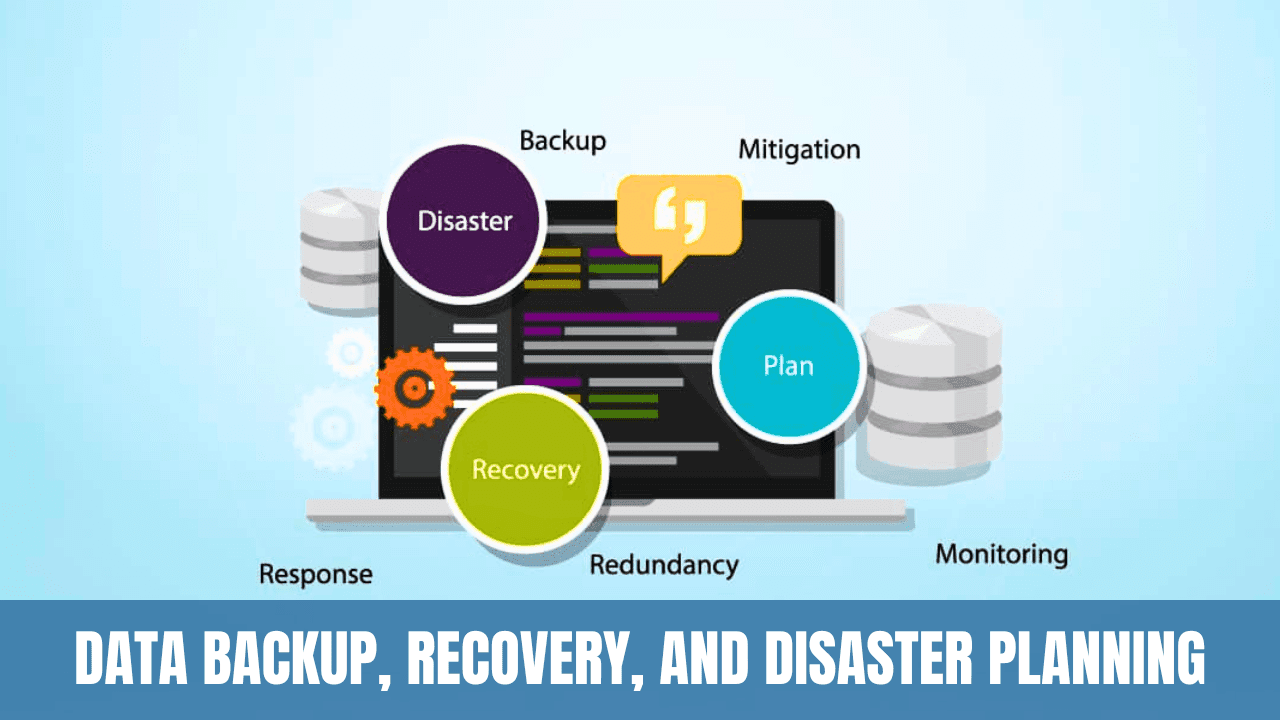
Data backup, recovery, and disaster planning are pivotal aspects of managing databases. Ensuring that data is secure, recoverable, and protected against unforeseen events is fundamental to the ongoing success and resilience of an organization. This article elaborates on these concepts and offers guidance on how to address questions related to them.
Section 1: Data Backup
1.1 Importance of Data Backup
Data backup is the process of copying or archiving files and databases to safeguard them.
- Prevents Data Loss: In case of accidental deletion or corruption.
- Facilitates Recovery: Enables restoration of data to a previous state.
1.2 Types of Data Backup
- Full Backup: Copies all data.
- Incremental Backup: Backs up only the changes since the last backup.
- Differential Backup: Backs up changes since the last full backup.
1.3 Backup Strategies
- Regular Backup Scheduling: Automated backups at consistent intervals.
- Remote Storage: Storing backups in geographically separate locations.
Section 2: Data Recovery
2.1 Understanding Data Recovery
Data recovery is the process of restoring lost or corrupted data.
- Immediate Action Required: Swift action can minimize data loss.
- Utilizing Recovery Tools: Specialized software can assist in data restoration.
2.2 Recovery Techniques
- Point-in-Time Recovery: Restoring data to a specific moment.
- File Level Recovery: Retrieving specific files or folders.
Section 3: Disaster Planning
3.1 Significance of Disaster Planning
Disaster planning involves strategies to minimize the impact of catastrophic events.
- Business Continuity: Ensuring ongoing operations despite a disaster.
- Risk Mitigation: Identifying and minimizing potential risks.
3.2 Developing a Disaster Recovery Plan
- Assessment: Identify essential systems and potential threats.
- Strategies and Procedures: Outline specific recovery steps.
- Regular Testing: Simulate disaster scenarios to test the plan.
3.3 Tools and Solutions
- Disaster Recovery as a Service (DRaaS): Cloud-based recovery solutions.
- High Availability Clusters: Systems that ensure uninterrupted services.
Conclusion
Data backup, recovery, and disaster planning are integral components of database management, contributing to the stability and resilience of an organization. By implementing well-defined strategies, utilizing appropriate tools, and regularly reviewing and testing these measures, organizations can ensure that their data remains secure and accessible, even in the face of unexpected challenges.
Whether addressing questions related to these topics or implementing them in practice, a systematic approach that encompasses understanding the needs, evaluating available options, and applying best practices will contribute to successful data management. It emphasizes the ongoing need for vigilance and adaptation in a rapidly changing technological environment.

Vishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy