Relational DB Transaction Management: Consistency, Integrity
Explore techniques for maintaining data consistency and integrity using transactions in relational databases. Understand the ACID properties and learn about locking mechanisms, concurrency control, log management, savepoints, and the two-phase commit protocol.

Transaction management is a fundamental aspect of relational databases, playing a crucial role in ensuring data consistency and integrity. Transactions are sequences of operations that act as a single unit, allowing multiple actions to be bundled together. This article explores the concept of transactions, their properties, and techniques to manage them within relational databases.
Section 1: Understanding Transactions
A transaction in a database context refers to a series of operations that are executed as a single unit. These operations usually include reading, inserting, updating, or deleting data.
Section 2: Properties of Transactions
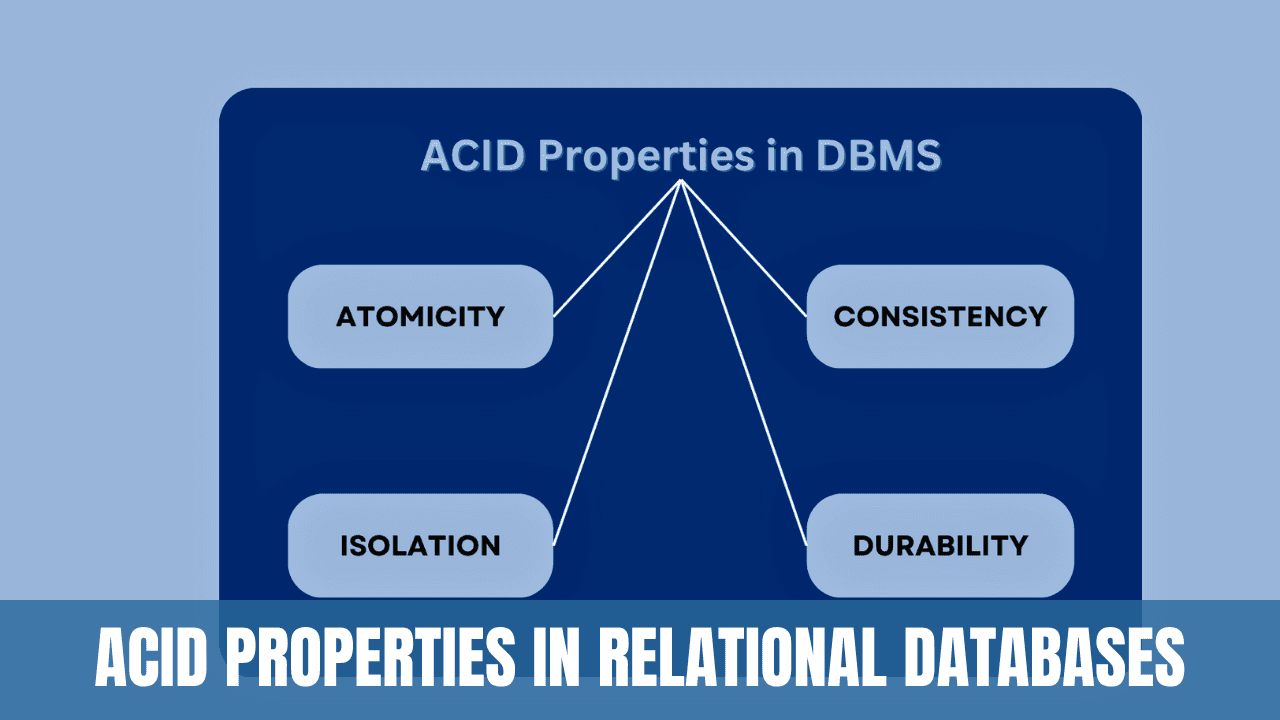
The properties of transactions are commonly referred to as ACID, which stands for Atomicity, Consistency, Isolation, and Durability.
2.1 Atomicity
Atomicity ensures that all operations within a transaction are completed successfully, or none are performed at all.
2.2 Consistency
Consistency ensures that a transaction brings the database from one consistent state to another, preserving the integrity constraints.
2.3 Isolation
Isolation ensures that concurrent transactions do not interfere with each other, allowing them to execute independently.
2.4 Durability
Durability ensures that once a transaction is committed, the changes are permanent and will survive system failures.
Section 3: Techniques for Transaction Management
3.1 Locking Mechanisms
Locking mechanisms prevent multiple transactions from accessing the same data simultaneously, thus maintaining consistency.
3.2 Concurrency Control
Concurrency control manages the simultaneous execution of transactions to ensure that the database remains in a consistent state.
3.3 Log Management
Log management involves keeping a record of all transactions, aiding in recovery in case of a system failure.
3.4 Savepoints
Savepoints allow transactions to be rolled back to a specific point, rather than the beginning, offering more control and flexibility.
3.5 Two-Phase Commit Protocol
The two-phase commit protocol is a method used in a distributed database system to achieve global transactions' consistency and integrity.
Conclusion
Transaction management is a complex yet essential aspect of relational database systems. By understanding and implementing techniques such as locking mechanisms, concurrency control, log management, savepoints, and two-phase commit protocols, data consistency and integrity can be maintained.
The ACID properties provide the foundation for understanding and managing transactions effectively. As relational databases continue to be a vital part of various applications and systems, mastering transaction management becomes imperative for database administrators, developers, and other professionals working with data.
The practices and techniques outlined in this article offer valuable insights and guidance for those looking to deepen their understanding of transaction management and its role in maintaining the robustness of relational database systems.

Vishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy