Text Classification with NLP: Simple Content Categorization
Text classification with NLP assigns predefined categories to text; the Python example uses scikit-learn to label news headlines as sports or technology. It requires installing scikit-learn, converts headlines into TF-IDF vectors, and trains a linear SVM. Accuracy is evaluated on labeled data not used during training.
Summary written with AI from this article, and checked against it.

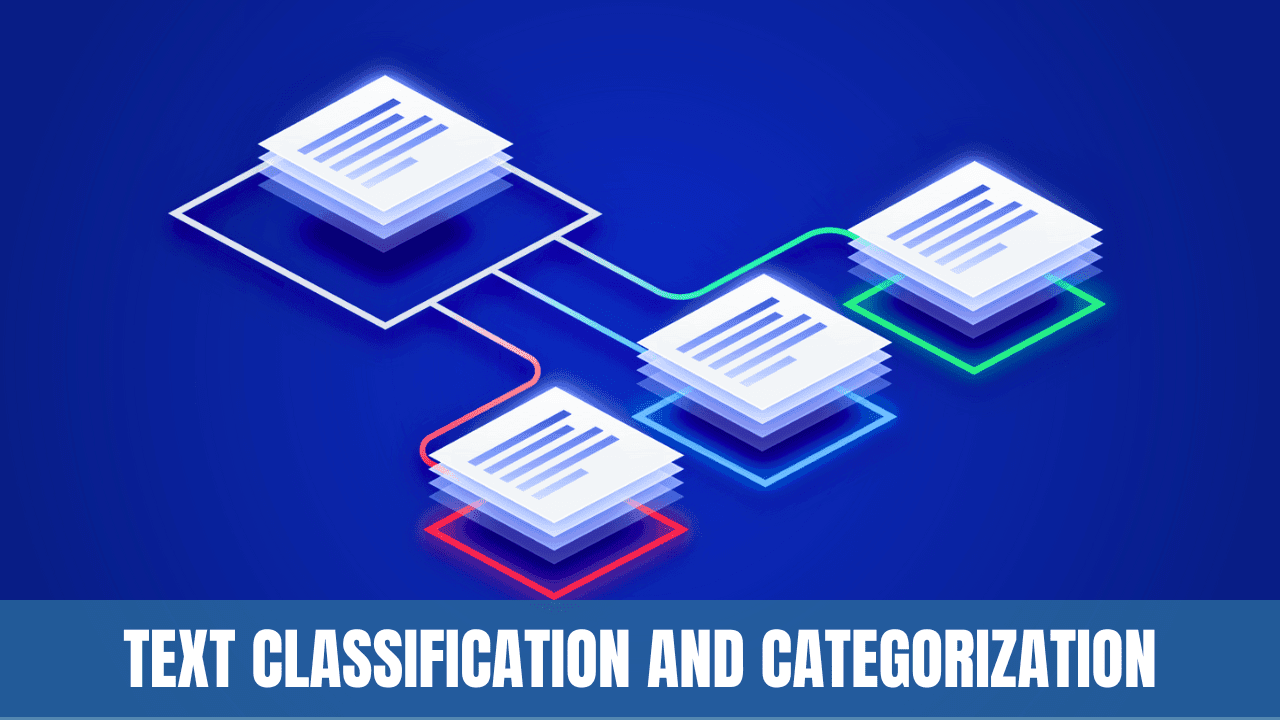
Text classification is a cornerstone of natural language processing (NLP). It involves assigning predefined categories, or tags, to textual content. From filtering emails as spam or not-spam to labeling customer reviews as positive or negative, the applications are extensive.
What is Text Classification?
Text classification, at its essence, is the act of categorizing text. Given a piece of text, the goal is to determine which of several categories it belongs to. These categories could range from simple binary decisions like "relevant" or "irrelevant" to more complex multi-class decisions encompassing numerous topics or sentiments.
NLP's Role in Text Classification
NLP techniques transform human language into data forms understandable by machines. This transformed data can then be analyzed and classified. Here's a simplified workflow:
- Preprocessing: Convert the raw text into a format suitable for analysis. This involves removing special characters, converting to lowercase, and stemming or lemmatizing words.
- Feature Extraction: Extract features from the text that will be useful for classification, often converting text into numerical vectors using methods like TF-IDF (Term Frequency-Inverse Document Frequency) or word embeddings.
- Model Training: With the numerical vectors representing the text, traditional machine learning algorithms like decision trees, SVM (Support Vector Machines), or neural networks can be trained to classify the text based on these vectors.
- Evaluation and Iteration: The model's accuracy is tested against a set of labeled data not used during training. Based on performance, the model might be refined and retrained.
Applications of Text Classification
- Spam Detection: Classify emails or messages as spam or not-spam based on content.
- Sentiment Analysis: Identify if a piece of text expresses a positive, negative, or neutral sentiment.
- Topic Labeling: Assign categories like "sports", "technology", or "health" to articles or documents.
- Language Detection: Determine the language in which a document or text snippet is written.
Let's use a basic example of text classification with Python's scikit-learn library to categorize news headlines into two predefined categories: "sports" and "technology".
Setting up:
First, ensure you have scikit-learn installed:
pip install scikit-learn
Example: Classifying News Headlines:
- Dataset:
Let's consider a small set of sample headlines and their respective categories:
headlines = [
    "New AI chip delivers faster processing speeds",
    "Lakers clinch playoff berth with victory",
    "Tech firms invest in quantum computing",
    "Soccer team wins international championship",
    "Innovative VR headset released in market",
    "Tennis star clinches grand slam title"
]
categories = ["technology", "sports", "technology", "sports", "technology", "sports"]
- Preprocessing and Feature Extraction:
We'll convert the headlines into numerical vectors using TF-IDF:
from sklearn.feature_extraction.text import TfidfVectorizer
vectorizer = TfidfVectorizer()
X = vectorizer.fit_transform(headlines)
- Training the Model:
We'll use a simple linear support vector machine (SVM) for classification:
from sklearn.svm import SVC
clf = SVC(kernel='linear')
clf.fit(X, categories)
- Predictions:
Now, we can predict the category of a new headline:
new_headline = ["Virtual reality in sports training"]
new_vector = vectorizer.transform(new_headline)
prediction = clf.predict(new_vector)
print(prediction[0])  # This might output 'technology'
Conclusion:
The example demonstrates how to preprocess text data, extract features, train a classifier, and make predictions. With a real dataset and more data points, the model can be optimized further to make accurate predictions. This basic workflow exemplifies the process of text classification using NLP techniques.
Text classification is a powerful application of NLP, offering a systematic approach to organize, tag, and understand vast amounts of textual data. Its principles and methods are fundamental for anyone looking to tap into the potential of NLP-driven categorization.

About the author
Vishal · Software & security engineerVishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy