Sentiment Analysis with Python: A Scikit-learn Example
Python and scikit-learn can classify text as positive or negative using CountVectorizer and a Naive Bayes model trained on labeled reviews. Install scikit-learn with pip install scikit-learn, then preprocess text, extract token counts and train the classifier. Accurate real-world results require a much larger dataset and more intricate preprocessing and modeling.
Summary written with AI from this article, and checked against it.

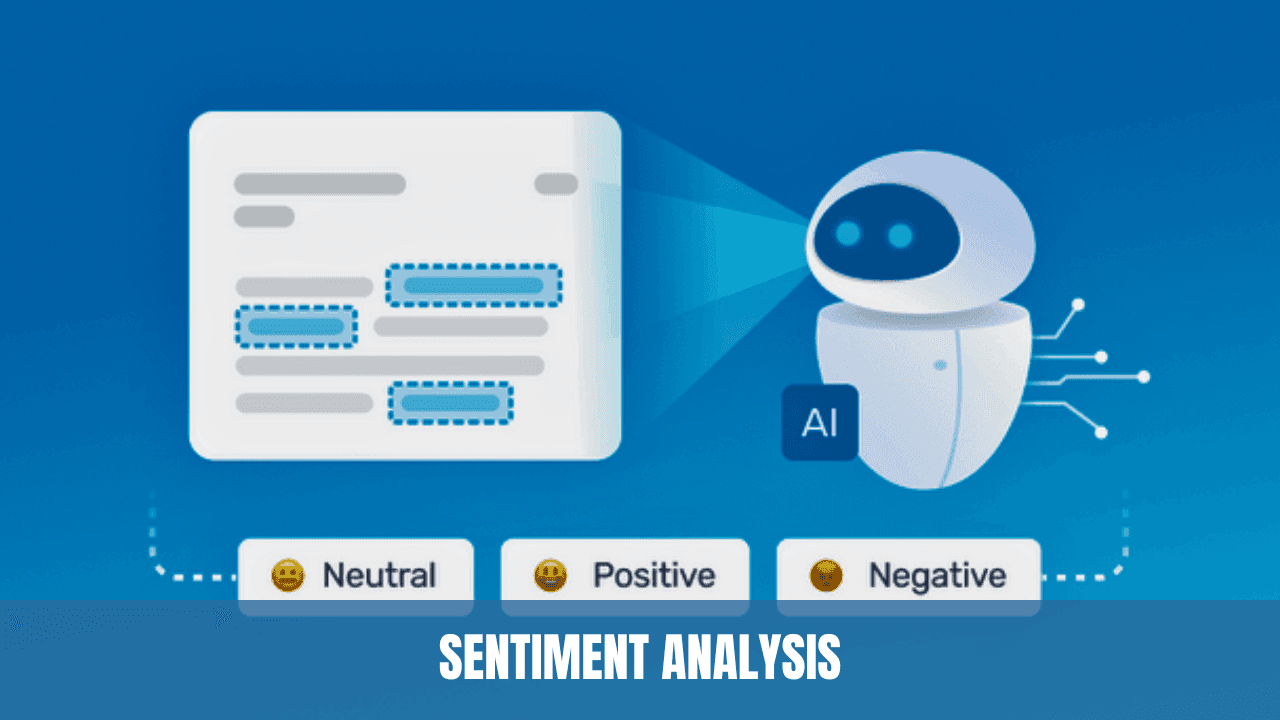
Sentiment analysis, often called opinion mining, is a technique in Natural Language Processing (NLP) used to determine the sentiment or emotion behind a piece of text. It can categorize opinions as positive, negative, or neutral. Businesses, especially those with an online presence, find sentiment analysis crucial for gauging customer feedback and refining their products or services. This article will explore some common techniques employed in sentiment analysis.
What is Sentiment Analysis?
At its core, sentiment analysis identifies and extracts subjective information from text sources. This could range from a customer's thoughts on a product to the public's opinion on a political event. The analysis gives a quantitative measure to these often qualitative expressions.
Techniques Used in Sentiment Analysis:
- Lexicon-Based Methods: This involves using a predefined list of words with assigned sentiment scores. The text is then analyzed based on the presence and frequency of these words. For example, the word "amazing" might have a positive score, while "terrible" has a negative one.
- Machine Learning Methods: These are automated techniques where a model is trained using labeled data. Popular algorithms for this purpose include:
- Naive Bayes: Often used for text classification tasks.
- Support Vector Machines (SVM): Known for its effectiveness in high-dimensional spaces.
- Deep Learning: Neural networks, especially Recurrent Neural Networks (RNN) and Long Short-Term Memory (LSTM) networks, are used due to their capacity to understand sequences, which is essential for text data.
- Hybrid Methods: These combine both lexicon-based and machine learning approaches. They can harness the strengths of both techniques to produce more accurate results.
- Aspect-Based Sentiment Analysis: Instead of looking at the sentiment of the entire text, this method identifies sentiments towards specific aspects or features. For instance, in a restaurant review, the food might be praised, but the service criticized.
Challenges in Sentiment Analysis:
- Sarcasm and Irony: Text containing sarcasm can be challenging to classify since the literal meaning is often opposite to the intended sentiment.
- Contextual Sentiment: The sentiment of a word can change based on the context. For example, "unpredictable" might be negative when talking about weather but could be positive in the context of a movie plot.
- Multi-Lingual Content: Different languages might require different sentiment analysis models due to linguistic nuances.
Let's delve into a basic example of sentiment analysis using Python and a popular machine learning library called scikit-learn.
Setting up:
To begin, you need to install the necessary libraries. You can do this using pip:
pip install scikit-learn
Example: Sentiment Analysis using Scikit-learn:
- Prepare the Data:
For simplicity, let's consider a small dataset:
reviews = [
"I love this product. It's amazing!",
"Quite disappointing. Expected better.",
"Does its job decently. Nothing extraordinary.",
"Terrible experience. Would not recommend.",
"The product is fantastic and works like a charm."
]
labels = [1, 0, 1, 0, 1] # 1 for positive sentiment, 0 for negative sentiment
- Text Preprocessing:
For this example, we'll use basic preprocessing: lowercasing and removing punctuation.
import string
def preprocess_text(text):
return text.lower().translate(str.maketrans('', '', string.punctuation))
processed_reviews = [preprocess_text(review) for review in reviews]
- Feature Extraction:
We'll use the CountVectorizer from scikit-learn to convert the text into a matrix of token counts.
from sklearn.feature_extraction.text import CountVectorizer
vectorizer = CountVectorizer()
X = vectorizer.fit_transform(processed_reviews)
Train a Model:
Let's use the Naive Bayes classifier:
from sklearn.naive_bayes import MultinomialNB
clf = MultinomialNB()
clf.fit(X, labels)
- Predict Sentiment:
Now, you can predict the sentiment of a new review:
new_review = "This is a brilliant invention!"
processed_new_review = preprocess_text(new_review)
X_new = vectorizer.transform([processed_new_review])
prediction = clf.predict(X_new)
if prediction[0] == 1:
    print("Positive Sentiment")
else:
    print("Negative Sentiment")
Conclusion:
This example provides a rudimentary insight into how sentiment analysis can be implemented using Python and scikit-learn. In real-world scenarios, a much larger dataset and more intricate preprocessing and modeling techniques would be employed to achieve accurate results.

About the author
Vishal · Software & security engineerVishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy