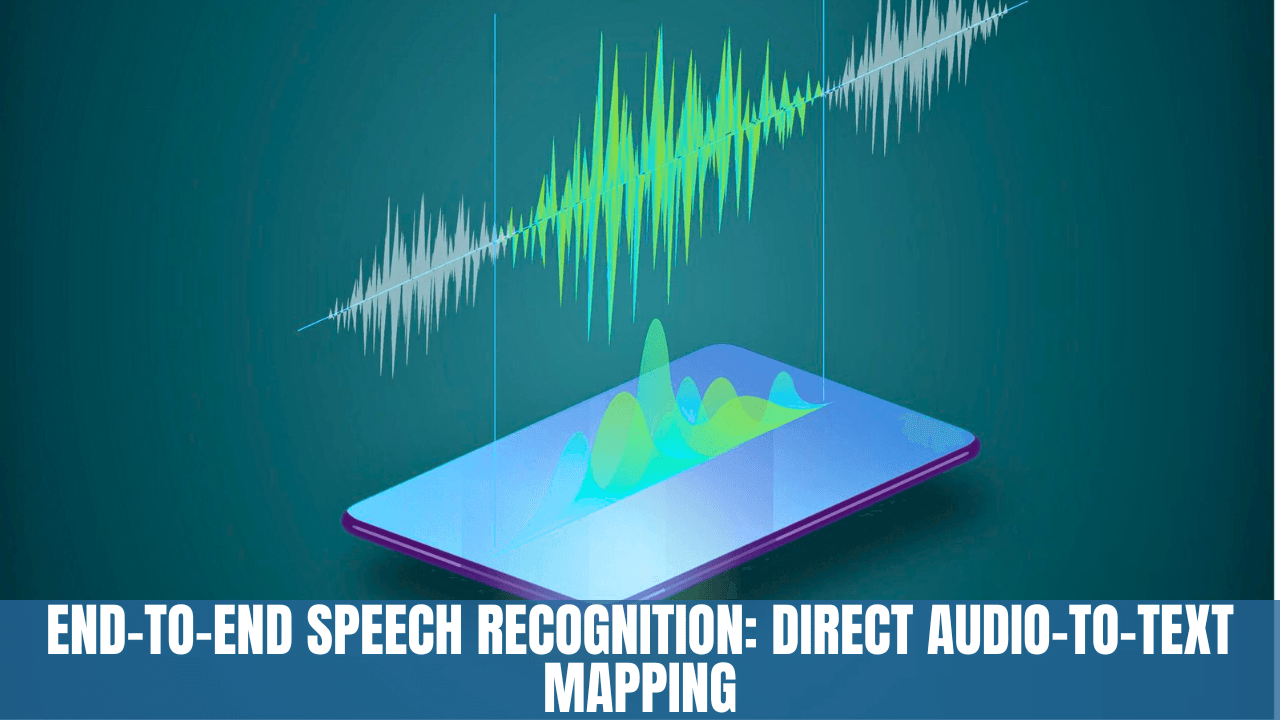
End-to-End Speech Recognition: Direct Audio-to-Text Mapping
Explore the efficiency of end-to-end speech recognition. Dive into how neural networks are revolutionizing the direct conversion of audio signals to actionable text, ensuring seamless real-time actions.

Speech recognition has evolved remarkably over the decades. Traditional models often required separate components for different stages of the recognition process, such as feature extraction and phoneme recognition. Enter the end-to-end speech recognition models. These innovative approaches have streamlined the process, offering a direct mapping from audio signals to text. Let's explore this further.
A Shift from Traditional Approaches
In the past, the journey of converting speech to text was complex. It started with the extraction of features from the audio signal. These features would then pass through various models to predict phonemes, words, and finally, complete sentences. Every stage had its model, and these were often trained separately.
Direct Mapping with Neural Networks
End-to-end speech recognition removes the intermediate steps. It uses deep neural networks to map audio features directly to text. No more separate models for phonemes or words. It's a direct leap from sound to sentence.
These neural networks, often recurrent neural networks (RNNs) or more advanced structures like Long Short-Term Memory networks (LSTMs), take in raw or minimally processed audio signals. As they process the signals, they predict the corresponding textual characters or subwords.
Advantages of End-to-End Approaches
- Simplicity: The primary advantage is the elimination of multiple modeling stages. This makes the system simpler and often faster.
- Unified Training: All components of the model are trained together, optimizing them for a single objective - accurate speech-to-text mapping.
- Flexibility: These models can easily adapt to different languages and accents, often without the need for language-specific tuning.
Challenges and the Road Ahead
Despite their advantages, end-to-end models are data-hungry. They require large amounts of labeled data to train effectively. There are also concerns about their ability to handle noisy environments or multiple speakers. However, with advancements in neural network architectures and training techniques, many of these challenges are being addressed.
Let's create a hypothetical scenario to illustrate how end-to-end speech recognition works in practice:
Scenario: Smart Home Integration
Setting: Jane, a tech enthusiast, recently upgraded her home with a variety of smart devices, including lights, thermostat, and security cameras. All these devices are controlled via a centralized smart home hub equipped with end-to-end speech recognition capabilities.
Action 1: As Jane enters her living room after a long day at work, she says, "Hey SmartHub, turn on the living room lights."
Without the need for a multi-stage process, the SmartHub's neural network directly processes Jane's voice, identifies the command and its context, and promptly turns on the lights.
Action 2: Feeling a bit chilly, Jane commands, "Hey SmartHub, set the thermostat to 72 degrees."
The SmartHub, using its end-to-end speech recognition, quickly maps the audio of Jane's voice directly to the text command, interprets it, and adjusts the thermostat accordingly.
Action 3: Later in the evening, Jane hears a noise outside. She instructs, "Hey SmartHub, show me the front door camera."
Without wasting time on intermediate steps, the SmartHub's neural network processes the command and promptly displays the feed from the front door camera on Jane's smart TV.
In each of these actions, the speech recognition is seamless. Jane doesn't experience any noticeable delay between her command and the SmartHub's response. This is the efficiency of end-to-end speech recognition: a direct and efficient mapping from audio signals to actionable text, facilitating real-time actions in diverse applications.
Conclusion
End-to-end speech recognition has ushered in a new era of simplicity and efficiency in converting audio to text. By leveraging the power of neural networks, this approach promises to continue improving, making speech recognition more accessible and accurate for all.

Vishal writes Trickyworld's tutorials and interview-preparation guides on programming, databases, cyber security and AI. Vishal has been shipping production software long enough to have firm opinions about Python, PHP, Node.js, and JavaScript, and to have been wrong about each of them at least once. The work has run the whole stack: Drupal and Laravel applications, React front ends, MySQL and MongoDB underneath, Redis and Memcached for the things that had to be fast, Apache Solr for the things that had to be findable. That last part turned out to matter more than anyone expected. Tune a Solr index for a season, then watch a language model confidently retrieve the wrong document, and you recognise an old problem wearing new clothes. Most of what is hard about AI systems is not the model. It is retrieval, caching, latency budgets, and deciding what the system does when the answer comes back wrong — which is work he has been doing since well before anyone called it AI engineering. He plays a lot of games, which is less a hobby disclosure than an admission of where a good share of his engineering instinct came from. Real-time systems with a frame budget. State that has to stay coherent while a player does something no designer anticipated. The permanent question of what happens when the frame cannot finish in time. Those habits carry over more directly than they have any right to. He has written several books on programming, all built on the same conviction: most technical writing is unclear because the author never decided what to leave out. More from Vishal → · Editorial policy